A backup vendor does not protect a critical alert. Control middleware does: a layer between the bank's systems and its messaging vendors that judges every message on its own delivery report, moves it to another operator or channel within a window set by how urgent the message is, and makes sure the customer does not receive it twice. Indian bank RFPs now ask for direct connectivity with at least three telecom operators, and many banks already run several SMS vendors on a primary, secondary and tertiary ladder. That ladder switches per vendor, often manually, so a single OTP can fail while its vendor still looks healthy.
Fyno works as a control middleware in five steps. It detects failure from the delivery report or a vendor error, not from the API's 200 OK. It classifies the failure, because a vendor timeout, an undelivered handset and a DLT template rejection each need a different response. It reroutes to the next operator or channel. It confirms delivery and suppresses duplicates. It logs every attempt against one reference ID, so that the complaint desk and the regulator get the same answer.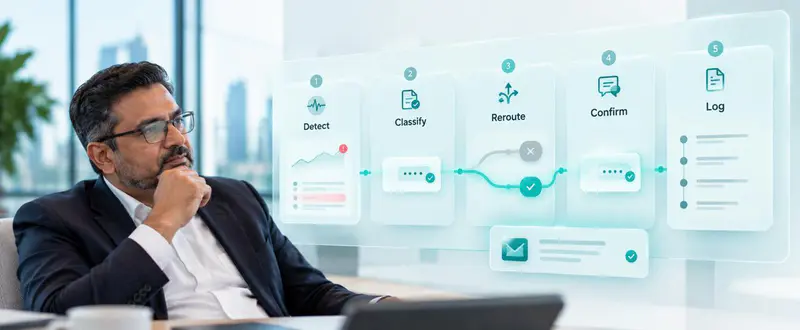
TLDR
Each section below opens with an answer that will help you understand if your failover detection and automatic rerouting technology stack is up to the mark. It also shows the mechanism. The first two define how to run the gateway, the last two how to improve vendor performance and cost.
What does smart failover between multiple operators or channels look like in practice?
How can error tracking and retries be managed intelligently in a messaging system?
How can businesses monitor and alert on anomalies in communication traffic?
How can businesses use delivery and read data to optimize message routing strategies?
How Fyno works as a control middleware.
What does smart failover between multiple operators or channels look like in practice?
Smart failover is decided per message, not per vendor. Each message type gets a wait window: seconds for OTPs, minutes for alerts, hours for marketing. If no delivery report arrives in time, the next operator or channel takes over, with duplicate checks so that the customer is not messaged twice.
Why a backup vendor is not the same as failover
A backup vendor is switched when the whole vendor is down. Most failures are smaller than that: one operator circle degrading, one international route silently dropping, one template being rejected at scrubbing. The vendor dashboard stays green while those messages fail. Per-message failover catches them because it watches each message's outcome rather than the vendor's status page.
Many banks also already run dispatch middleware that checks DLT templates and forwards traffic to vendors. That is not the same thing. Control middleware adds the decision layer: it reads every outcome and acts on it.
Bank IT teams raise the same concerns. As one small finance bank architect put it: "If it is not delivered in 5 seconds, then you go to another provider... but it is also possible that when we switch it, both SMS will be delayed or both get delivered." If the first message lands after a failover has already sent a second, the customer receives the same OTP twice. That is why de-duplication belongs inside the middleware, not after it.
What control middleware does, step by step
A worked OTP example
The OTP goes to the primary SMS route for the customer's operator.
The wait window for OTPs is short, within 5-15 seconds and pays nothing for a late or undelivered message
No delivery report arrives within the window, so the message goes out again through an alternate SMS carrier on a different route.
If that route also returns no delivery, the message moves to WhatsApp, with email as the last step for non-time-critical alerts.
If the first SMS lands late, the duplicate is suppressed and every attempt is logged against one reference ID.
The cascade runs in one direction. A critical message starts on SMS, moves to an alternate SMS carrier if the first route does not deliver, then to another messaging channel such as WhatsApp, and only after that to email. Email sits at the end because it is the slowest to be seen, not because it is unmeasurable: it returns submitted, delivered, read, opened and clicked, and an invalid address returns its own response, so the middleware knows whether that last attempt landed.
A switched-off handset is not a blind spot either. SMS returns a status showing the number was unreachable, so the message can be rerouted. WhatsApp holds the message on its servers and hands it over when the customer next opens the app. What no reroute fixes is a wrong or dead number, which is why invalid numbers are better caught before dispatch than after.
How can error tracking and retries be managed intelligently in a messaging system?
Classify the error before acting on it.
Submission errors, such as vendor timeouts or 5xx responses, can be retried once and then failed over. Undelivered reports mean the operator or handset failed, so reroute instead of resending. Template rejections need fixing, not retrying. Log every attempt against one reference ID.
Four failure classes, four responses
Rejections deserve their own row. Under TRAI's November 2025 direction, variables in SMS templates must be pre-tagged by data type and purpose, and messages that do not match are rejected. A retry loop that does not recognise this will resend a message that can never pass.
Fyno’s built-in DLT template approvals. BFSI institutions can create the template, submit to DLT, track approval, all from Fyno. Variable tags applied at creation. Approved templates auto-whitelisted. and audit trail makes it easy to reduce delivery failures and prove delivery in case of consumer disputes.
How can businesses monitor and alert on anomalies in communication traffic?
Monitor per vendor, operator, destination and template, not in aggregate: failures hide in averages. Alert on sudden delivery drops, missing callbacks, traffic falling to zero and OTP spikes on one number or country. Tier severity to avoid noise. For OTPs, multi-vendor and multi-channel routing has improved delivery rates to near 100% in BFSI.
Alerts and monitoring a bank needs for delivery failure detection
Guardrails and alerts
A burst of OTP requests to one number is either a fraud attempt or a customer stuck in a loop, and banks handle it with a guardrail rather than a judgement call. The common pattern is a limit of three to five OTP requests, then a cooldown of 30 minutes to an hour before that number can ask again, the same way a phone locks after repeated wrong passcodes. Requests past the limit are rejected with a message telling the customer there have been too many attempts.
Two things make this work. The limit and the cooldown are business rules the bank sets, so they can differ by product. And enforcement is automatic, with nobody waiting for a person to approve a block. Alerting sits alongside the guardrail, so that a spike on one number, prefix or department also reaches the team that needs to see the pattern, not just the customer who is locked out.
Keep the noise down
A bank sending tens of millions of messages a month cannot act on an alert for every failed message. Severity tiers help: an isolated failure is logged, a pattern on one route is escalated. Fyno's dashboard grades alarms as High, Medium, Low or Info, and surfaces anomalies such as sudden volume spikes, significant deviations from historical traffic and unexpected provider behaviour. Anomaly alerts flag outliers in the workspace's traffic trend using a 90th-percentile method and go by email to up to five addresses, so that the risk team can receive them directly.
How can businesses use delivery and read data to optimize message routing strategies?
Compare vendors on the same traffic: delivery rate, time to deliver and callback accuracy per operator and circle. Evaluate every send, deprioritise underperformers automatically, and let the bank's own rules govern the split. Reconcile invoices against delivered counts. Reserve read-based failover for non-critical messages.
Two layers: automatic deprioritisation inside bank-owned rules

Routing works on two layers at once. At the send level, "live delivery rates, latency, and vendor health inform every routing decision" and "underperforming vendors are automatically deprioritised". At the rule level, the bank decides the logic: percentage splits, conditions by message type, destination or customer segment, and the order of failover. Bank teams build and change these journeys themselves as needs evolve, on a no-code canvas.
Commercial reality shapes the rules. Aggregators often ask for a minimum share of traffic, and price still drives many split decisions. The rules should reflect those contracts; the automatic layer then protects delivery inside them.
Delivery data is also billing evidence
Delivery reports are the only independent record of what a vendor actually delivered. Indian Bank's SMS RFP sets a 98% success-rate floor and charges ₹1,000 for every false delivery report. A bank can only enforce clauses like that if it measures delivery itself, across vendors, in one place.
Where read data fits
Read receipts exist for WhatsApp, email, push and in-app, but not for SMS. Use them for non-critical messages: if a statement reminder is read in the app, the SMS never needs to go. For OTPs and transaction alerts, wait for delivery, not reads, because the first message has already cost money and the time window is short.
How Fyno works as control middleware
Fyno is the Communication Orchestration Platform for BFSI: control middleware that sits downstream of a bank's core data systems, CCM and Martech, and upstream of CPaaS. It runs the five steps across every vendor the bank already uses, without replacing any of them.
Detect: Fyno detects vendor downtime in real time, compares vendors on delivery and latency, and raises anomaly, integration failure and callback failure alerts.
Classify: the most common permanent failure is stopped before it happens. DLT templates are created with TRAI variable tags, validated before submission and tracked to approval inside Fyno.
Reroute:Fyno automatically switches to a pre-configured backup vendor, and underperforming vendors are deprioritised on every send. The rules around that stay with the bank: vendor preferences, failover conditions and cross-channel escalation are set on a visual canvas.
Confirm: Fyno blocks duplicate sends across LOS, LMS, and CRM before they leave", and undelivered messages are not billed.
Log:one audit trail per message across vendors, with vendor invoices reconciled against Fyno's delivery records in real time.
Summary
A backup vendor protects against a vendor outage. Control middleware protects each critical alert, message by message.
Control middleware works in five steps: detect, classify, reroute, confirm, log.
Classify before retrying. Template rejections and handset failures are not fixed by resending.
Duplicate suppression is part of failover, not an afterthought.
Monitor per route and alert on drops, missing callbacks, zero traffic and OTP spikes. Alert on OTP anomalies; do not auto-block.
Delivery data reweights vendors inside bank-owned rules and is the evidence behind RFP penalty clauses.